Document OCR & Field Extraction
Structured unstructured documents in, typed fields out.
- Client
- Confidential
- Year
- 2024
- Category
- AI
- Role
- Design + Build
- Timeline
- 3–5 weeks
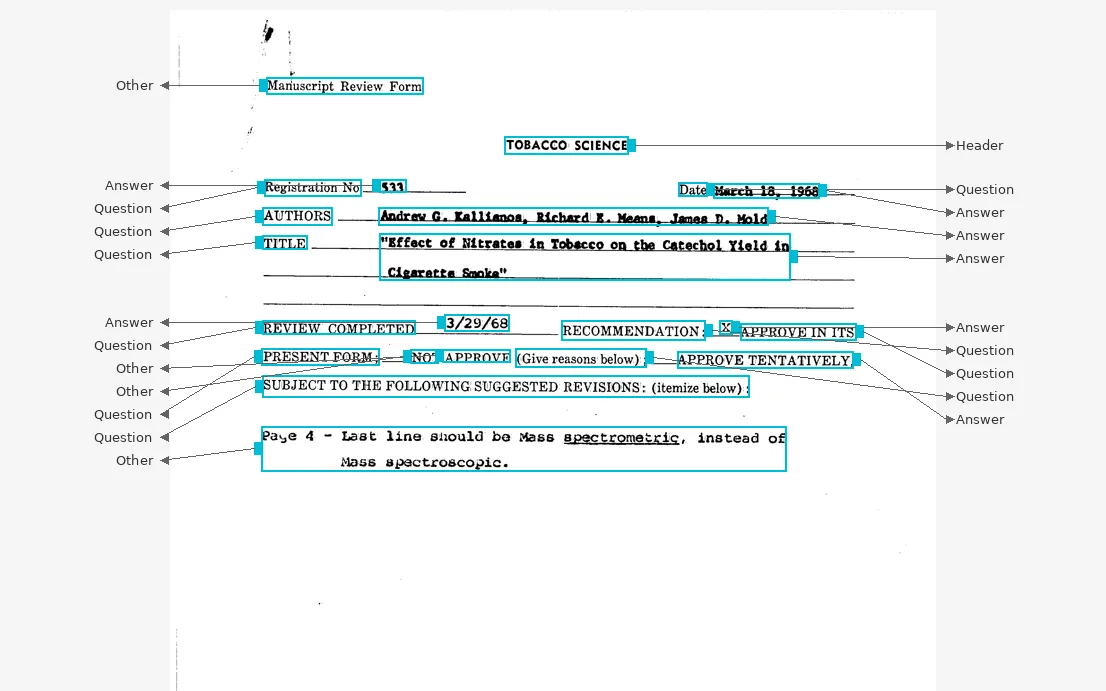
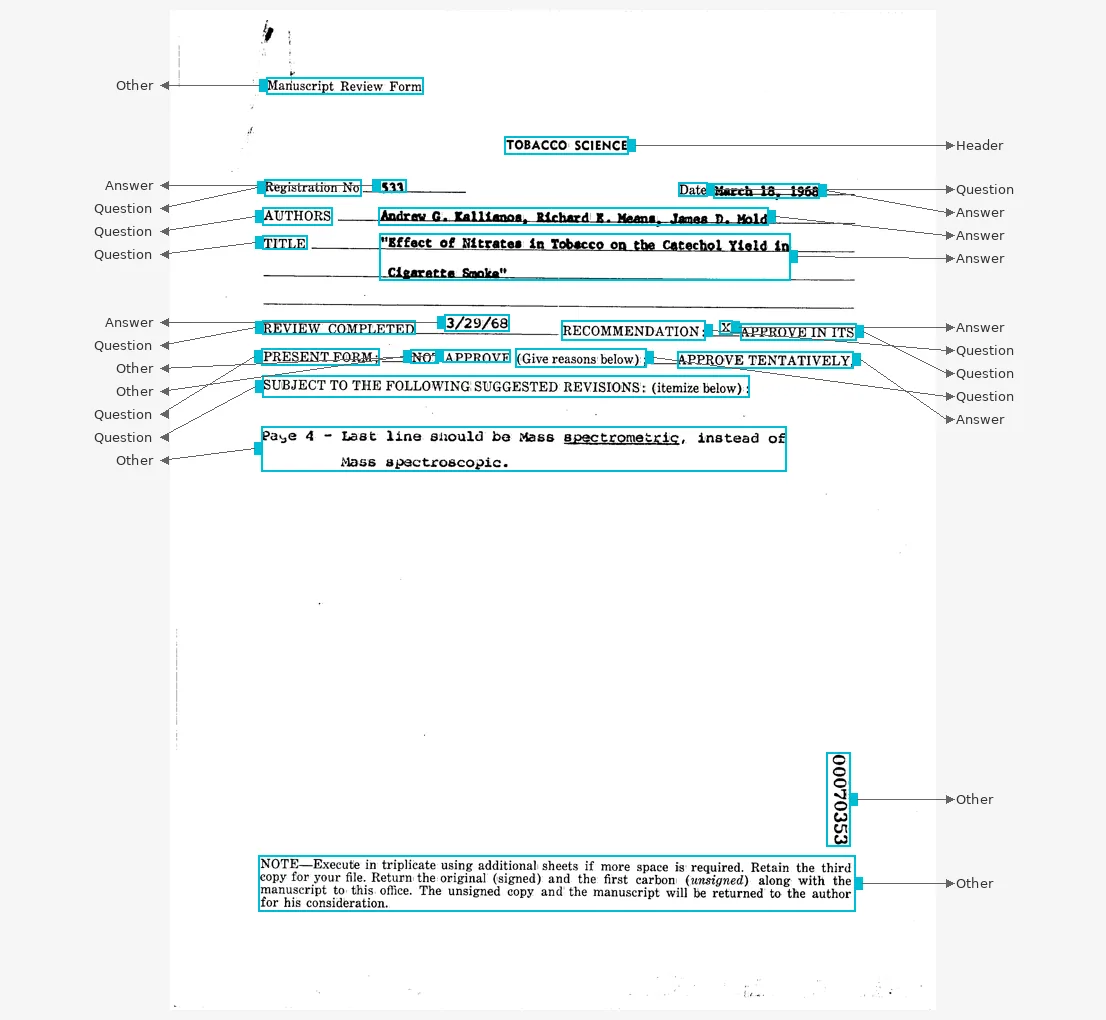
Structured unstructured documents in, typed fields out.
Key data was locked in scanned documents and PDFs, re-keyed by hand. Slow, and every re-key is another chance to introduce an error.
OCR to lift the text, then a field-extraction layer that maps it to the fields that matter, each with a confidence score. A details view surfaces the low-confidence extractions for a human to confirm, so the pipeline is fast where it’s sure and careful where it isn’t.
Documents become data on arrival, and the people who used to re-key them now just check the uncertain ones.
Built with
We deliver what we commit.
We'll come back within 24 hours with honest feedback on scope, timeline and cost, whether or not we turn out to be the right fit.